Featured Articles
displayMode
carousel
filter
paths
paths
From Root Cause To Pull Request: AI SRE in Splunk Observability Cloud Can Now Remediate Incidents With Claude Managed Agents
Splunk is extending AI SRE in Splunk Observability Cloud from incident diagnosis to code-level remediation.
Splunk Blogs
.conf26
displayMode
carousel
filter
paths
paths
/en_us/blog/security/evolving-to-autonomous-defense-new-agentic-soc-capabilities
/en_us/blog/observability/cisco-empowers-organizations-to-govern-ai-at-scale-with-full-stack-observability
/en_us/blog/conf-splunklive/defending-at-machine-speed-in-the-ai-era
/en_us/blog/partners/2026-splunk-regional-partner-award-winners
/en_us/blog/observability/network-intelligence-app-new-network-visibility-in-splunk-synthetic-monitoring
/en_us/blog/conf-splunklive/move-beyond-golden-signals-to-curated-business-journeys
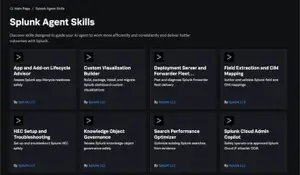
/en_us/blog/artificial-intelligence/splunk-cli-and-agent-skills
Evolving to Autonomous Defense: New Agentic SOC Capabilities
Splunk is expanding its Agentic SOC Workforce with a set of new purpose-built skills, across detection, investigation, response, and governance.
Cisco Data Fabric
displayMode
carousel
filter
paths
paths
/en_us/blog/platform/splunk-platform-innovations-cisco-data-fabric-generally-available
/en_us/blog/platform/escaping-the-cloud-walled-garden
/en_us/blog/platform/machine-data-lake-and-catalog
/en_us/blog/platform/making-machine-data-easier-to-onboard
/en_us/blog/platform/a-general-purpose-lakehouse-is-not-enough-for-machine-data
/en_us/blog/platform/escaping-the-cloud-walled-garden
/en_us/blog/platform/machine-data-lake-and-catalog
/en_us/blog/platform/making-machine-data-easier-to-onboard
/en_us/blog/platform/a-general-purpose-lakehouse-is-not-enough-for-machine-data
Escaping the Cloud Walled Garden
Three Critical Gaps in Multicloud Machine Data—and How Cisco Data Fabric Closes Them
Artificial Intelligence
displayMode
carousel
filter
paths
paths
Introducing Splunk Agent Launchpad: Turn Operational Signals Into Agent-Powered Action
Announcing the general availability of Splunk Agent Launchpad, a no-code way of building agents within your Splunk environment with your RBAC.