Pratik Bhavsarのブログ投稿
Pratik Bhavsar is an AI Engineer at Splunk focusing on agent evaluation, reliability, and observability. He has spent a decade building across the full AI stack, from training transformers, building semantic search, and shipping ML systems to designing agentic architectures.
He joined Cisco through the acquisition of Galileo, where he led open-source evaluations and developer relations. He built the Agent Leaderboard, an open benchmark measuring AI agent performance on real-world tasks, and the Hallucination Index, a systematic study of factual reliability across foundation models.
He is the author of five technical books covering eval engineering, agentic systems, RAG, multi-agent architectures, and LLM-as-a-Judge methodologies. Prior to Galileo, Pratik was a founding NLP Scientist at Enterpret and Senior Data Scientist at Morningstar. Pratik holds an M.Tech from IIT Bombay and loves to share his thoughts on Substack.
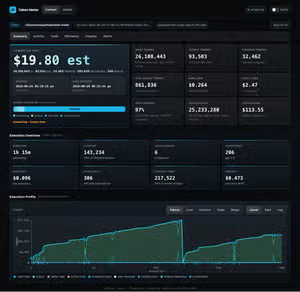
エージェントトークノミクスとは?