Agentic Observability from Day One: From OpenTelemetry to AI Agents.
Observability Yogesh KulkarniKey takeaways
- Instrumenting applications with OpenTelemetry from the start, rather than waiting for production, makes it much easier to trace and fix errors quickly.
- AI agents require tracking new signals like token usage and model calls, since an agent can technically work while still being slow, costly, or low quality.
- Splunk Observability Cloud Free Edition lets developers experiment with monitoring tools like Agent Observability without needing a full production deployment first.
A couple of years ago, I wrote about a modern way of developing distributed applications using Open Telemetry (OTel).
At the time, generative AI was not nearly as mainstream as it is today; we were mostly familiar with distributed application problems: Which service is slow? the request fails? Why is one API waiting for another?
From RAG Observability to Agent Observability
Last year, I shared how we built end-to-end LLM observability for a RAG-based AI Assistant. That experience taught me an important lesson: building an AI application is only part of the job. You also need to understand what happens between the user's question and the final answer—retrieval, context, model calls, latency, quality, token usage and everything in between.
But AI applications are evolving again.
A RAG application may retrieve context and ask an LLM to generate an answer. An agent can go further—it can decide what to do next, invoke tools, call services, retrieve additional information, interact with other agents and adapt its path along the way.
That means our observability needs to evolve with the application.
For me, Agent Observability isn't a replacement for the LLM and RAG observability practices I wrote about previously. It's the next layer.
Distributed observability helped me understand the path of a request.
RAG observability helped me understand the path of an answer.
Agent Observability helps me understand the path of a decision.
Applications are becoming more distributed, more dynamic, and now increasingly agentic. A single interaction can span over microservices, APIs, LLMs, tools and agents before a user ever sees a response.
But many of us are still debugging them the old way.
We wait for something to break. We search for logs. We jump between systems. We try to reconstruct what happened after the fact.
That approach was already becoming difficult with distributed applications. With agentic applications, it just does not scale!
The way we build applications has changed. The way we observe them needs to change too.
Observability shouldn't be something the engineering team adds when an application is ready for production. It should be part of how we develop the application from Day One—just like testing, source control, and CI/CD.
We treat unit tests this way. Why shouldn't we treat observability the same way?
And with agentic applications, I think this becomes even more important.
Recently, I tried Splunk Observability Cloud Free Edition, which gives developers a way to start experimenting with observability—including Agent Observability—without waiting for a production deployment.
That was enough to get me excited. So rather than talk about observability in theory, let's build something and see what happens.
Why Start with Observability?
In the past, it was easy to think of observability as something for production—a platform that another team would configure later.
That excuse is getting harder to make.
With Splunk Observability Cloud Free Edition, I can instrument the application I'm developing today and start learning from its telemetry without waiting for a production environment or a large observability project.
The barrier to starting is low, and the payoff is high.
Think about a relatively simple distributed application.
A user makes one request, but behind that request there may be an authentication service, token service, API, database, and several other dependencies.
From the user's perspective, it is one click.
From an engineer's perspective, it might be:
User → API → Authentication → Token Service → Backend Service → Database → Response
Now imagine that request fails.
You can certainly start opening logs. Find the request in one service, grab an ID, move to another system, search again, and continue connecting the dots.
I've done it. We all have. But there is a better way.
Logs Aren't Dead—But Logs Alone Are No Longer Enough
Logs are still incredibly valuable. But in today's distributed applications, looking at individual logs often gives us only one piece of the story.
What I really want to understand is the journey of the request.
Which services did it touch?
Where did it spend its time?
Which call failed?
What happened immediately before the failure?
That's where traces become extremely useful.
Instead of asking:
"Which log should I search next?"
I can follow a request through the application and see how the pieces connect.
And the good news is that getting started doesn't have to be a multi-day project.
Let's Get a Real Application into Splunk Observability Cloud
For this experiment, I wanted to instrument the application I was already developing—not a special demo application.
The process was surprisingly straightforward.
Step 1: Start With Splunk Observability Cloud Free Edition
Create a free Splunk Observability Cloud environment.
My goal here wasn't to create the perfect production observability architecture. I simply wanted somewhere to send telemetry while I was developing locally.
Step 2: Go Back to Your Code
Now take the application you are actually working on.
In my case, the application consists of multiple services, including supporting services such as authentication and token services.
Step 3: Add OpenTelemetry Instrumentation
Instrument the application with OpenTelemetry.
One of the things I like about OTel is that observability doesn't have to become tightly coupled to application business logic.
For supported technologies, auto-instrumentation can do a surprising amount of work for you.
Tip: If you use an AI coding assistant, the otel-instrument skill from Splunk Observability Studio can add Open Telemetry instrumentation for you.
Step 4: Configure the Splunk Environment
Point your Open Telemetry exporter at your Splunk Observability Cloud realm and give it an access token, so your telemetry has somewhere to go. For sending data, use an org access token with the ingest scope, not your personal user API token.
See the org access tokens documentation for how to create one.
Step 5: Run Your Application
Build and run the application.
I am a big believer in being able to run as much of the complete application locally as possible.
Today, AI-assisted development makes this considerably easier. Tasks such as creating Docker configurations, wiring local dependencies, and troubleshooting configuration issues no longer need to consume an afternoon.
Repeat the instrumentation for the other services involved in the transaction.
Step 6: Generate Some Traffic
Call a few endpoints.
Break something if you want.
Then comes my favorite part.
Ready for the magic?
Open Splunk Observability Cloud.
From Services to One Request
The first thing I can see is the application as a collection of services.
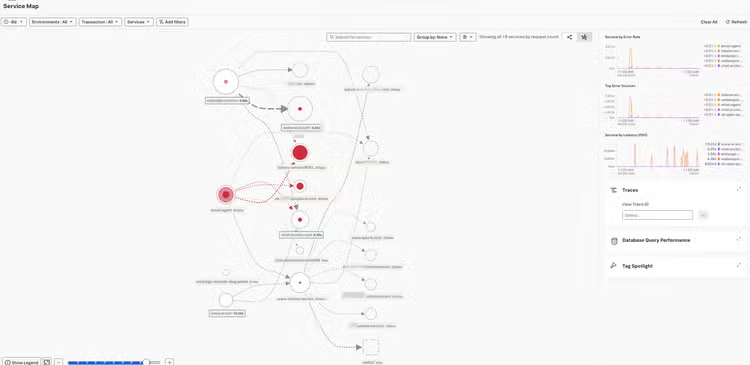
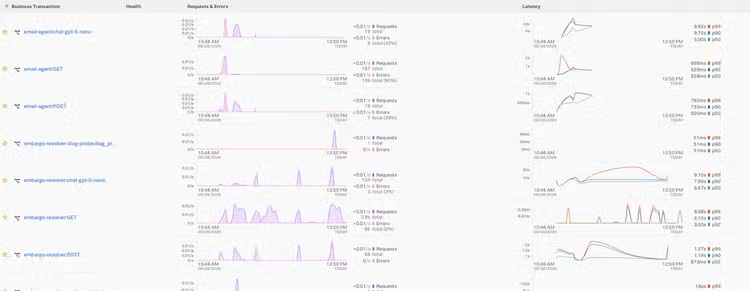
Now I can select one service and immediately start looking at its requests, errors, and latency.
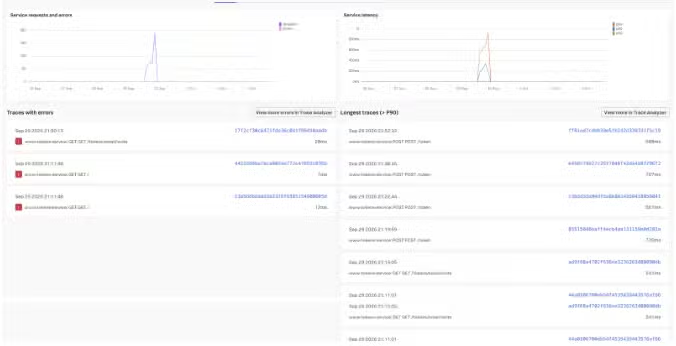
But the interesting part is going to another level deeper.
I can select an individual trace and follow that request across the services involved in processing it.
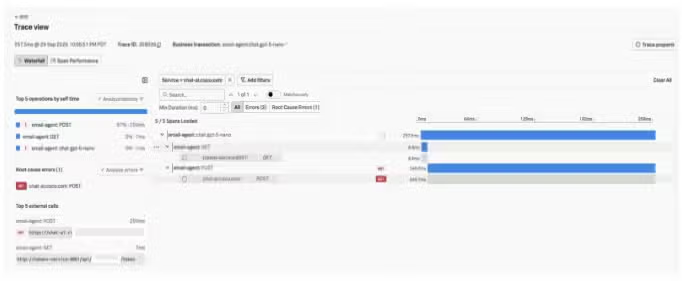
This is where observability starts changing the development experience for me.
Here's a real example from my own build. One of my agent's chat spans was flagged with an error. Instead of searching logs, I opened the trace: the call to the token service succeeded in about 7 MS, but the very next call, the POST to the LLM endpoint, came back with a 401 after about 250 MS. Two spans and one glance told me to look at how the token was being passed to the model's endpoint, not at the agent's logic.
I'm no longer trying to reconstruct what happened from disconnected pieces of information. I have the context of the request.
And then I started adding an AI agent. That's when things got even more interesting.
What Changes When Your Application Has an Agent?
A traditional distributed transaction might look something like this:
User → Service → Service → Database → Response
An agentic transaction can look very different:
User → Agent → LLM → Tool → Service → Agent → LLM → Response
And that's still a simple example.
An agent might make several LLM calls, invoke multiple tools, retrieve information, reconsider an earlier decision and call another agent before returning anything to the user.
Suddenly my old debugging questions aren't enough.
I still need to know:
- Did a service fail?
- Where was the latency?
- Did an API return an error?
But now I also want to know:
- What did the agent do?
- Which model did it call?
- Which tools did it use?
- How long did those calls take?
- How many tokens did the interaction consume?
- What input did the model receive?
- What response came back?
- Did the overall interaction produce a good result?
This is why Agent Observability doesn't replace application observability. It extends it.
Enter Agent Observability
Agentic AI goes beyond the traditional request/response interaction with an LLM.
An agent can understand a goal, plan how to accomplish it, invoke tools and adapt based on what happens along the way.
That's powerful.
It's also exactly why we need visibility into what the agent is doing.
For my experiment, I connected the agent I was developing to Splunk Agent Observability.
One important architectural point is that I didn't want to lose the observability I had just built for the rest of my application.
I wanted both.
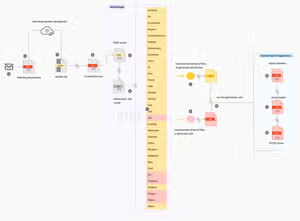
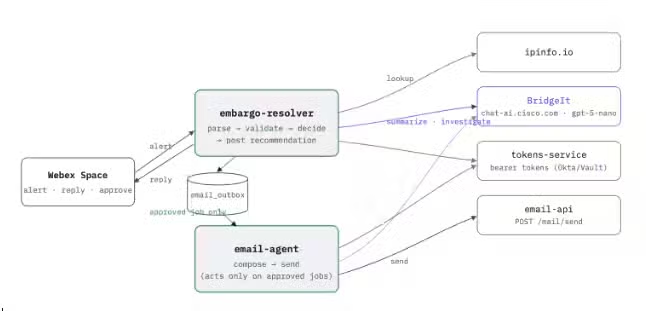
My app is a small two-agent workflow. When an automated check flags a case, a resolver agent gathers independent evidence, makes a recommendation and posts it to a chat space for a human to review. Only after a person approves does a second agent compose and send a follow-up email. Both agents call an LLM, a token service, and a few external APIs, so the app is a good mix of regular distributed calls and agentic decisions.
Figure: Architecture of my sample agentic app: two agents, a deterministic verdict core, and a confidence-gated step into autonomous evidence gathering.
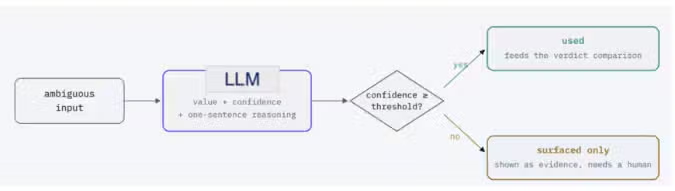
The model investigates ambiguity. A threshold decides if that's enough.
The same application still has APIs, services, and infrastructure that need traditional observability. The agent introduces another layer that needs its own visibility.
That combination is where things become useful.
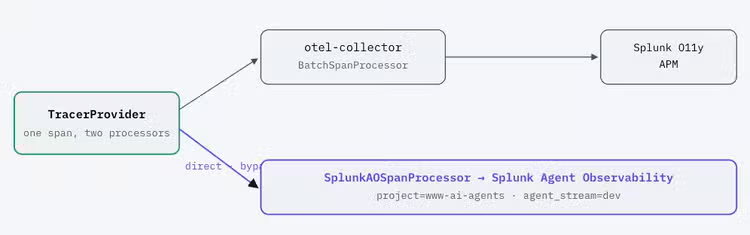
The Gotcha: Every Span Has to Go Two Places
Here's the one thing I wish I had known up front. Splunk Observability Cloud APM and Splunk Agent Observability are separate products with separate ingest endpoints. My existing OpenTelemetry pipeline sent spans through the collector to APM, and that kept working perfectly. Agent Observability, meanwhile, saw nothing, and nothing told me why.
The fix is to register a second span processor on the same TracerProvider, so every span is exported twice: once through the collector to APM, and once directly to Agent Observability. Remove that second processor and APM keep working while Agent Observability silently goes dark.
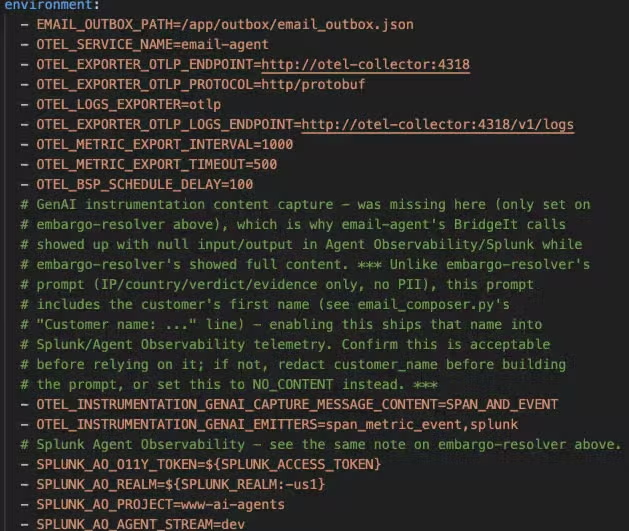
Two attributes made the agent data much more useful: gen_ai.agent.name, so I could tell my two agents apart, and gen_ai.conversation.id, so calls from both agents for the same case are grouped into one session. Use a stable, non-personal identifier for the conversation ID, such as a hashed case ID, rather than a user's IP address or email.
More on the GenAI config : https://help.splunk.com/en/splunk-observability-cloud/observability-for-ai/splunk-ai-agent-monitoring/configure-ai-agent-monitoring/configure-the-python-agent-for-ai-applications-0.1.14-and-higher
Now Follow the Agent
Once agent telemetry starts flowing, I can see the agents I'm running.
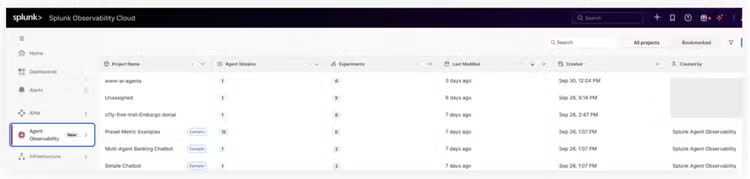
From there, I can move into the agent stream and see individual interactions.
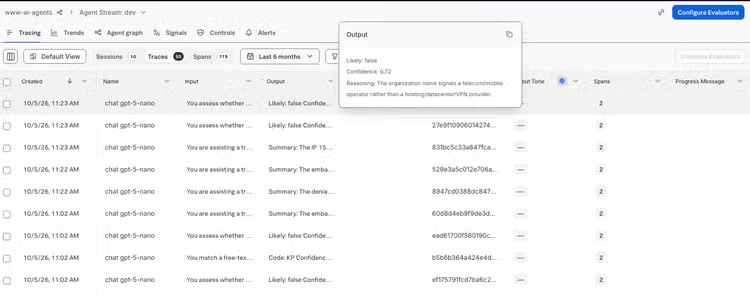
And then I can drill into one interaction.
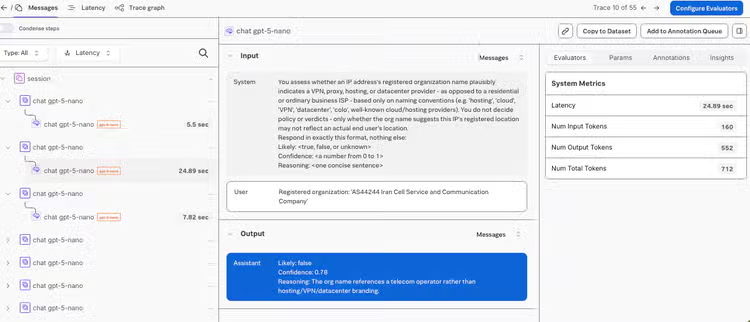
This is my second "aha!" moment.
With the agent, observability helps me understand the path of a decision.
Now I can begin looking at the agent's inputs and outputs alongside operational information such as latency and token usage.
That matters because an agent can technically "work" and still have problems.
Maybe the answer is correct, but it requires far too many model calls.
Maybe latency suddenly doubled.
Maybe a tool was invoked unnecessarily.
Maybe token consumption increased after a prompt change.
Or perhaps the agent returned a perfectly fast answer that simply wasn't very good.
Those are different problems—and we need visibility to tell them apart.
Token Usage Is Now an Observability Signal
This is another change I think developers need to get used to.
In traditional application development, I spend a lot of time looking at CPU, memory, response time, errors and throughput.
With AI applications, tokens become another operational signal.
Here's a real example. In the interaction shown above, the agent wrote a short customer email of three to six sentences. It used 480 input tokens and 1,221 output tokens, with 8.76 seconds of latency. That's more than twice as many tokens out as in for a few sentences of text, most likely because the model spends tokens reasoning before it writes. Nothing was broken, and no log would have told me. But on scale, that ratio is a cost and latency decision I want to make on purpose.
If a prompt change causes every request to consume substantially more tokens, that's worth knowing.
If one workflow requires several LLM calls while another accomplishes the same task with two, that's worth knowing too.
Cost, performance, and quality are increasingly connected.
Evaluating Agent Quality Beyond Traditional Metrics
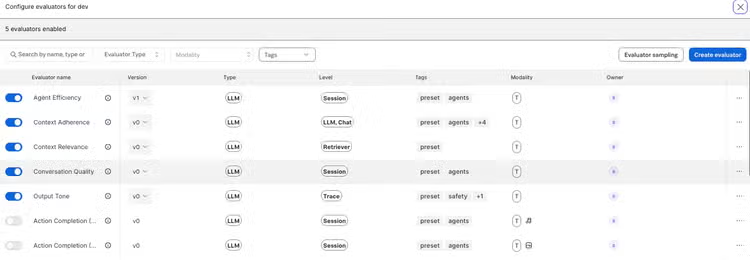
Agent Observability goes beyond monitoring latency, errors, and token consumption. It also allows us to configure evaluators that assess how effectively an AI agent performs its tasks.
In this example, I've enabled five evaluators: Agent Efficiency, Context Adherence, Context Relevance, Conversation Quality, and Output Tone.
These evaluators help answer questions that traditional monitoring cannot: Is the agent using relevant context? Is its response grounded in the retrieved information? Is it completing tasks efficiently? And is the overall conversation meeting quality expectations?
This is an important shift—from simply observing whether an application works to evaluating how well an AI agent actually performs.
Observability Should Be Part of the Development Loop
Don't wait until your application reaches production.
Instrument it while you're building it.
- Run the complete workflow locally when possible.
- Generate traffic.
- Follow traces.
- Break things.
- Watch what your agent does.
- Change prompt and see what happens to latency, tokens and behavior.
- Change a tool and follow the interaction again.
This turns observability from something we use primarily when production is broken into something we use while developing the application.
And I think that's especially important for agentic systems because their behavior isn't always as deterministic as the applications we're used to building.
This is exactly why Splunk launched Observability Studio open-source Observability Studio (ObStudio) gives developers a local workspace to receive, explore, and validate OpenTelemetry data as they build. Its audit and instrumentation tools help identify coverage gaps before they reach production.
It turned out to be useful for exactly the problem above: my traces showed up in Agent Observability but not in Studio, and the assistant worked through which local OTLP endpoints were listening to track down why.
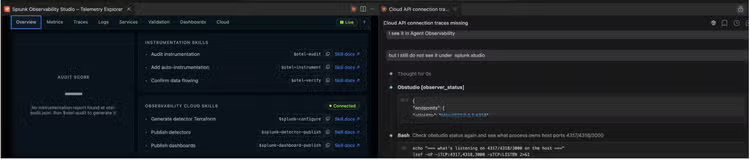
This is an area I plan to continue exploring because I think there is another interesting convergence happening:
We are using AI to build applications.
We are putting AI inside those applications.
And now we can use AI-assisted tooling to help us understand whether those applications are observable in the first place.
That's a topic worthy of another post.
Start Small
You don't need a massive multi-agent production system to start learning Agent Observability.
- Start with an application you already have.
- Instrument one service.
- Add another.
- Follow a trace.
Then instrument your agent and follow one interaction from the user's question through the model and tools and back to the response.
The important part isn't how complicated your first example is.
It's building the habit of asking:
"Can I understand what my application just did?"
If the answer is no, adding more agents isn't going to make that easier.
Final Thoughts
A few years ago, observability helped us make sense of increasingly distributed applications.
Now those applications are becoming increasingly agentic.
The fundamental problem hasn't changed: when something happens inside our system, we need enough context to understand what happened, where it happened, and why.
What has changed is the journey we're trying to understand.
It is no longer always just:
Request → Service → Database → Response
It may now be:
Request → Agent → Model → Tool → Service → Agent → Model → Response
That makes observability more important, not less.
My biggest takeaway from this experiment isn't a feature or a dashboard.
It's a change in how I think we should build software.
We don't write an application and add testing at the very end. We don't wait until production to put our code into source control. Observability should increasingly follow the same model.
Instrument while you build. Observe while you develop.
This was already valuable for distributed applications. As we move into agentic applications—where a single interaction may involve services, models, prompts, tools, tokens and decisions—it becomes even more important.
And today, the barrier to getting started is remarkably small. Splunk Observability Cloud Free Edition gives developers a way to experiment without turning it into a large infrastructure project.
So don't wait for your first production incident to discover what your application is actually doing.
Build it. Instrument it. Break it locally. Follow the trace. Understand the decision, token usage, token cost. Then ship it with confidence.
Related Articles
Threat Advisory: Telegram Crypto Botnet STRT-TA01
Breaking the Chain: Defending Against Certificate Services Abuse